Proxmox Cluster Setup Guide: Build Shared Storage, Quorum, and HA in a Supportable Order
Build a small Proxmox cluster in a supportable order: hardware baseline, quorum, shared storage, HA behavior, and the network choices that keep failover predictable.
Disclosure: This article may contain affiliate links. If links are added or updated on this page, HomelabAddiction may earn a commission at no additional cost to the reader. No personal testing claim is made by this disclosure.
Documentation basis: This guide is grounded in the Proxmox cluster manager, storage, and HA manager documentation. The sequence below is framed around documented quorum, migration, and failover behavior rather than anecdotal success stories.
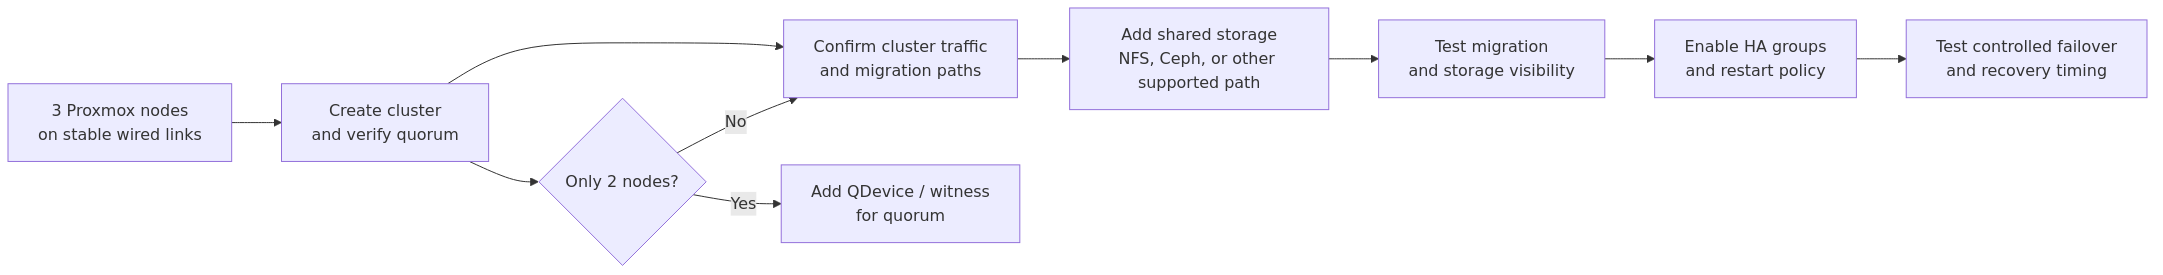
A small Proxmox cluster is easiest to support when the build order stays disciplined: start with stable wired nodes and clean quorum, then add shared storage, then add HA only after migration and restart behavior have been tested.
That order matters because most cluster pain comes from layering HA on top of unfinished storage or network assumptions. The platform works best when each dependency is proven before the next one is introduced.
This guide keeps the sequence documentation-led so operators can verify what should happen during node loss, migration, and recovery instead of depending on folklore.
Key Takeaways
Three similar wired nodes are the cleanest starting point for quorum and migration.
Shared storage is what turns clustering from a control-plane experiment into a practical maintenance tool.
HA should be enabled only after migration, restart timing, and service dependencies are verified.
Backups remain mandatory because HA protects availability, not data integrity or operator mistakes.
Build order for a small Proxmox cluster: establish clean node networking and quorum first, then add shared storage, then enable HA only after migrations and restart behavior are verified.
When a Proxmox cluster is worth the complexity
Before building a cluster, decide whether the environment truly benefits from quorum, shared storage, and migration workflows. A cluster adds useful resilience patterns, but it also adds more moving parts than a single-node deployment.
Cluster makes sense when:
- You want to learn enterprise virtualization patterns
- You need HA for services that can't go down (home automation, DNS, security cameras)
- You want to do maintenance without downtime
- You're running mixed workloads that benefit from resource pooling
- You want to experiment with distributed storage (Ceph)
Single node is better when:
- Your budget is tight and you'd rather spend on one good machine
- You're running a simple media server and file storage
- You don't need live migration or failover
- You want simplicity over redundancy
If the decision is still unclear, a single node is often the better starting point. Clustering later is possible, but it goes more smoothly when the first node already has clean storage boundaries, documented networking, and a realistic backup plan.
Hardware Requirements for a Proxmox Cluster
You don't need enterprise hardware to build a functional cluster. But you do need to be intentional about what you buy.
Minimum Requirements Per Node
Component
Minimum
Recommended
CPU
64-bit with VT-x/AMD-V
Intel 8th gen+ or AMD Ryzen
RAM
8 GB
16-32 GB
Storage
120 GB SSD
256 GB+ NVMe
Network
1 GbE
2x 1 GbE (or 1x 2.5 GbE)
Power
Whatever you have
Low-power mini PC (under 15W idle)
Build Tiers
Budget Build (~$300 total):
Three used Dell OptiPlex Micro or Lenovo ThinkCentre Tiny machines. You can find 8th-gen Intel i5 units with 8GB RAM for $80-100 each on eBay. Add a cheap gigabit switch and you're in business.
Mid-range starting point (~$600 total): three efficient mini PCs with wired Ethernet, NVMe storage, and enough RAM for the expected VM count usually provide a better learning platform than one oversized tower that still lacks quorum and migration behavior.
Premium Build (~$1,000+ total):
Three Intel NUC 12/13 Pro or Minisforum MS-01 units with 32GB RAM each, 1TB NVMe, and 2.5GbE networking. If you're running Ceph, this is the tier to aim for.
Matching nodes simplify CPU compatibility, storage symmetry, and capacity planning. Three similar nodes are usually easier to operate than a mixed collection that all need separate migration caveats.
Hardware Gotchas
Mixed hardware can work, but plan around CPU compatibility and migration targets early. When Intel and AMD nodes are mixed, choose a CPU type that keeps live migration predictable instead of assuming host passthrough will behave the same everywhere.
Network ports matter. Each node needs at minimum one gigabit Ethernet port, but two is strongly recommended. One for management/VM traffic, one dedicated to cluster communication. More on this in the networking section.
Network Design: The Foundation Most Guides Skip
This is where most Proxmox cluster guides fail. They tell you to "create a cluster" and "join nodes" without explaining how your network should be designed. Bad networking is the number one cause of cluster instability.
The Three Networks You Need
Your cluster should have three logical networks (they can share physical NICs with VLANs, or use separate NICs):
Management Network - For accessing the Proxmox web UI, SSH, and API
Cluster Network - Dedicated to Corosync heartbeat traffic (this is critical)
Storage Network - For NFS/Ceph traffic between nodes and storage
Simple Approach: Two NICs Per Node
If you have two NICs per node (or two VLANs), here's the minimum viable setup:
For either approach, the key rule is: Corosync traffic must not compete with VM or user traffic. Corosync is extremely sensitive to latency and packet loss. If it detects network instability, it may trigger a node fence - which means your VMs get killed and restarted on another node. Not ideal for a Saturday afternoon.
transmission signup
article_topic // Proxmox Cluster Setup Guide
Don't leave without the setup notes.
Get practical homelab guides, failure logs, and beginner-friendly build notes in your inbox.
Enter your email address to receive the Homelab Addiction newsletter.
Weekly only. No spam. Unsubscribe anytime.
Why Wi-Fi Is Never Okay
Do not use Wi-Fi for cluster traffic. Corosync expects low-latency, low-jitter communication, and intermittent wireless latency spikes are enough to create noisy quorum behavior.
Step-by-Step: Creating Your Proxmox Cluster
With hardware and networking settled, the next step is to create the cluster and verify that each node can see the others consistently before storage or HA is layered on top.
Prerequisites Checklist
Before you start, make sure every node has:
# Verify all nodes can reach each other
ping 10.0.2.11  # From node 1 to node 2
ping 10.0.2.12  # From node 1 to node 3

# Verify time sync (critical for Corosync)
timedatectl status
# Should show "NTP service: active"

# If NTP isn't active, enable it
apt install chrony -y
systemctl enable --now chrony

# Verify /etc/hosts has all nodes
cat /etc/hosts
# Should contain:
# 10.0.2.10  pve1
# 10.0.2.11  pve2
# 10.0.2.12  pve3
Creating the Cluster (First Node)
On your first node (this becomes the primary):
Via GUI:
1. Open https://pve1:8006
2. Go to Datacenter → Cluster → Create Cluster
3. Enter a cluster name (e.g., "homelab")
4. Select the cluster network (your dedicated cluster NIC/IP)
5. Click Create
Via CLI (faster):
# On node 1 (pve1)
pvecm create homelab --link0=10.0.2.10
The CLI approach gives you more control over network links. The --link0 parameter specifies the IP address Corosync uses for this node.
After creation, the first node generates a join information file. You'll need this for the other nodes.
Joining Nodes to the Cluster
Via GUI:
1. On node 2, go to Datacenter → Cluster → Join Cluster
2. Paste the join information from node 1 (or scan the QR code)
3. Enter the root password of node 1
4. Click Join
Via CLI:
# First, get the join information from node 1
pvecm qnet setup

# Then on node 2, join the cluster
pvecm add 10.0.2.10

# Repeat on node 3
pvecm add 10.0.2.10
Verify the Cluster
After all nodes are joined, verify everything is healthy:
# Check cluster status
pvecm status

# Expected output should show:
# Membership information
# ----------------------
#     Nodeid      Votes    Name
#          1          1    pve1
#          2          1    pve2
#          3          1    pve3

# Check quorum
pvecm expected
# Should show: 2 (majority of 3 nodes)

# Test node communication
pvecm nodes
If you see all three nodes and the quorum is 2, your cluster is healthy. If something's wrong, check that your firewall allows UDP ports 5404-5412 on the cluster network.
Firewall Rules for Cluster Traffic
On each node, ensure these ports are open on the cluster interface:
# Corosync cluster communication
iptables -A INPUT -i eth1 -p udp --dport 5404:5412 -j ACCEPT
# Or for all cluster-related traffic
iptables -A INPUT -i eth1 -p udp --dport 5404:5412 -j ACCEPT
iptables -A INPUT -i eth1 -p tcp --dport 22 -j ACCEPT
Or use the Proxmox firewall GUI: Datacenter → Firewall → Add rule for the cluster network.
Understanding Quorum and the 2-Node Problem
Quorum is the mechanism that prevents split-brain - a situation where two halves of your cluster think they're the authoritative one. It works on a simple majority vote.
How Quorum Works
With 3 nodes, you need 2 nodes to agree (majority). If one node goes down, the other 2 maintain quorum and keep running. With 5 nodes, you need 3. And so on.
With 2 nodes, you need... well, you need both. That's the problem. If one node goes down, the remaining node can't form a majority (1 out of 2 isn't a majority). So both nodes stop, and your cluster is dead.
The QDevice Solution
A QDevice (quorum device) is an external witness that provides an extra vote. This makes a 2-node cluster viable because the QDevice tips the balance.
Setting up a QDevice with a Raspberry Pi:
# On the Raspberry Pi (running Debian/Ubuntu)
sudo apt update
sudo apt install corosync-qnetd -y
sudo systemctl enable --now corosync-qnetd

# On each Proxmox node
pvecm qdevice setup <raspberry-pi-ip>
That's it. The Pi becomes your third "voter" without running any actual workloads. A Pi Zero 2 W ($15) is perfect for this - it draws almost no power and just sits there watching.
Important: The QDevice needs to be on the same low-latency network as your cluster nodes. Don't put it on a different subnet or across a VPN. It needs to respond to Corosync within milliseconds.
Baseline recommendation
If you can afford 3 nodes, go with 3 nodes. The QDevice approach works, but it adds another point of failure and another device to maintain. Three physical nodes with proper quorum is simpler and more reliable.
Shared storage: what turns clustering into a practical operations tool
Here's a truth that surprises many homelabbers: without shared storage, a Proxmox cluster is just centralized management. You can't live migrate VMs, you can't fail over automatically, and you can't do rolling maintenance. All the cool stuff requires shared storage.
Option 1: NFS (Simplest)
NFS is the easiest shared storage to set up. You need a NAS (Synology, TrueNAS, or a Linux box with NFS) and each Proxmox node mounts the same NFS share.
# On your NAS, export a directory
# /etc/exports on a Linux NAS:
/vmnt/proxmox 10.0.2.0/24(rw,sync,no_subtree_check,no_root_squash)

# On each Proxmox node
mkdir -p /mnt/nfs-proxmox

# Add to /etc/fstab for persistence
echo "nas.local:/vmnt/proxmox /mnt/nfs-proxmox nfs defaults 0 0" >> /etc/fstab
mount -a
Then in Proxmox GUI: Datacenter → Storage → Add → NFS. Enter the NAS IP and path.
Pros: Simple, works with any NAS, no special hardware
Cons: Single point of failure (the NAS), NFS performance can be limited
Option 2: Ceph (Best for HA)
Ceph is a distributed storage system that runs directly on your Proxmox nodes. Each node contributes storage, and Ceph replicates data across nodes. If one node dies, your data survives.
# On each node, install Ceph
pveceph install

# Initialize the first monitor
pveceph init --network 10.0.2.0/24

# Create a monitor on each node
pveceph mon create

# Add OSDs (storage disks) on each node
# Replace /dev/sdb with your actual disk
pveceph osd create /dev/sdb

# Create a storage pool
pveceph pool create homelab-pool --pg_num 128
Pros: Distributed (no single point of failure), scales with nodes, thin provisioning
Cons: Needs 3+ nodes minimum, requires more disk space for replication overhead
Option 3: ZFS Replication (Middle Ground)
If you have ZFS on each node, you can set up periodic replication between nodes. It's not true shared storage, but it gives you a backup path for failover.
# Create a ZFS replication job in Proxmox GUI
# Datacenter → Storage → Add → ZFS
# Or via CLI:
pvesm add zfs zfs-replica \
  --pool rpool/data \
  --nodes pve1,pve2,pve3 \
  --replicate 15m
This replicates VM disks every 15 minutes. If a node dies, you can restore from the replicated copy on another node. It's not instant failover, but it's better than nothing.
Storage Recommendation
For most homelabs: NFS on a dedicated NAS is the pragmatic choice. It's simple, well-documented, and your NAS is probably already running. If you want true HA with automatic failover, Ceph is the way to go - but make sure you have at least 3 nodes with identical (or similar) storage.
NFS is often the simplest way to learn shared storage behavior first. Ceph can be the better long-term fit when the cluster has enough nodes, disks, and operational patience for distributed storage, but it should be added intentionally rather than by default.
High availability: how to make failover predictable
HA in Proxmox means: if a node dies, its VMs automatically restart on another node. But HA has requirements that many guides gloss over.
HA Requirements
A working cluster (obviously)
Shared storage - VMs must be on NFS/Ceph, not local disks
An HA group - defines which nodes are eligible for failover
HA resources - tells Proxmox which VMs to protect
Setting Up an HA Group
# Via CLI
ha-manager group create production \
  --nodes "pve1:1,pve2:1,pve3:1" \
  --type group

# Or via GUI: Datacenter → HA → Groups → Create
The :1 after each node name is the priority. Lower numbers = higher priority. So pve1:1 means "try to run VMs on pve1 first."
Adding VMs to HA
# Via CLI
ha-manager config set vm:100 \
  --group production \
  --max_restart 3 \
  --max_relocate 1

# Via GUI: Datacenter → HA → Resources → Add
# Select your VM, assign to the HA group
max_restart 3: If the VM fails to start, try up to 3 times
max_relocate 1: If restart fails on the current node, try relocating once
Testing Your HA Setup
This is the part most guides skip. Don't just configure HA and hope it works. Test it.
The Pull-the-Plug Test:
1. Start a VM on node 1 and note its IP
2. Start a continuous ping: ping <vm-ip>
3. Physically unplug node 1's power (or network)
4. Watch the ping - you should see a brief interruption (30-90 seconds)
5. The VM should restart on node 2 or 3
6. Verify the VM is accessible again
The Graceful Shutdown Test:
# On the node running the VM
pveam shutdown pve1

# Watch the HA manager restart it on another node
ha-manager status
Test HA in a lab-like window before depending on it for important services. Controlled failover tests expose boot-order assumptions, storage lag, and service startup dependencies that are easy to miss in a static configuration review.
From the lab
Live Migration: Moving VMs Without Downtime
Live migration is the ability to move a running VM from one node to another without interrupting services. It's one of the main reasons to cluster.
How to Live Migrate
Via GUI:
1. Right-click the VM → Migrate
2. Select the target node
3. Check "Online" for live migration
4. Click Migrate
Via CLI:
# Live migrate VM 100 from pve1 to pve2
qm migrate 100 pve2 --online

# With bandwidth limit (useful for large VMs)
qm migrate 100 pve2 --online --bw-limit 100
When Live Migration Fails
Live migration requires:
- Shared storage (VM disk must be accessible from both nodes)
- Compatible CPU types (use x86-64-v2-AES for mixed hardware)
- Sufficient resources on the target node
- Network connectivity between nodes
If migration fails, check:
# Check if the VM is on shared storage
qm config 100 | grep scsi

# Check target node resources
qm status  # Shows running VMs
pveam status  # Shows HA status

# Check migration logs
journalctl -u pveproxy | grep "migrate"
Monitoring Your Cluster
A cluster without monitoring is a cluster waiting to surprise you. Here's what to watch:
Built-in Monitoring
# Quick cluster health check
pvecm status

# Watch Corosync health
corosync-cfgtool -s

# Check for fencing events
journalctl -u pve-fencing

# Ceph health (if using Ceph)
ceph health detail
ceph osd tree
Setting Up Prometheus + Grafana
For real monitoring, deploy Prometheus on one node and Grafana on another. Key metrics to track:
Corosync ring latency (should be under 5ms)
Quorum status (should always show "quorate")
Ceph OSD health (all OSDs should be "up" and "in")
Node CPU, RAM, and disk usage
VM resource consumption
Cluster monitoring should make quorum, node reachability, storage health, and restart failures visible in one place. A small dashboard or alert set is enough as long as it surfaces the signals that explain why failover did or did not behave as expected.
Common Mistakes (and How to Avoid Them)
These are the mistakes that most often make small Proxmox clusters feel unreliable even when the platform itself is behaving as documented:
1. Using Wi-Fi for cluster traffic. Already covered this, but it bears repeating. Ethernet only.
2. No shared storage. People build a cluster and then keep VMs on local disks. You've just added complexity with zero benefit. If you're not ready for shared storage, stay single-node.
3. Jumbo frames without validation. If you enable jumbo frames (MTU 9000) on your cluster network, you must verify it end-to-end:
# Test jumbo frame path between nodes
ping -M do -s 8972 -c 4 10.0.2.11

# If this fails, jumbo frames aren't configured correctly on every hop
# (switch, both NICs, and both nodes)
4. Forgetting about backups. HA protects against node failure, not corruption, operator mistakes, or bad updates. Shared storage and failover do not replace a tested backup and restore routine.
5. Not testing failover. Configure HA and walk away is the most dangerous thing you can do. Test it. Break things on purpose. Make sure it works before you need it.
6. Ignoring split-brain. If your cluster loses quorum (more than half the nodes go down), it stops fencing and shuts down VMs. This is correct behavior - it prevents two halves of the cluster from running the same VM. But you need to understand it and have a recovery plan.
Maintenance and Rolling Upgrades
One of the best features of a cluster is the ability to update nodes without downtime. Here's the process:
# 1. Migrate all VMs off the node you want to update
qm migrate <vmid> <target-node> --online

# 2. Verify the node is empty
qm list  # Should show no VMs on this node

# 3. Put the node in maintenance mode (optional but recommended)
ha-manager node maintenance <node-name>

# 4. Update the node
apt update && apt dist-upgrade -y

# 5. Reboot if needed
reboot

# 6. After reboot, verify the node rejoins the cluster
pvecm status

# 7. Remove from maintenance mode
ha-manager node free <node-name>

# 8. Migrate VMs back (or leave them distributed)
Repeat for each node. Your VMs stay running the entire time. This is why clustering is worth the setup effort.
Cost Analysis: Is Clustering Worth It?
Let's do the math for a typical 3-node homelab cluster:
For comparison, a single enterprise server capable of similar workloads (32+ cores, 96GB+ RAM, redundant power) would cost $2,000-5,000 and draw 200-400W. A 3-node cluster of mini PCs is cheaper, uses less power, and gives you actual redundancy.
Recommended Hardware
If hardware is being selected now, prioritize predictable NICs, enough RAM per node, and storage that matches the migration and HA plan instead of shopping only by raw CPU score.
New in the store: If this cluster is going into a rack, the Home Lab Rack Planner helps you lay out node position, switch space, UPS fit, depth, and power distribution before you order the hardware. It is $11.99 with code EARLY20 instead of $14.99, limited to the first 50 purchases.
Beelink SER5 Max Mini PC (Ryzen 7 5800H) - strong small-node option with enough CPU headroom, NVMe support, and reasonable idle power for lab clustering if the surrounding networking and backup plan are already sound.
TP-Link TL-SG2008P Managed Switch - 8-port gigabit with 4 PoE+ ports and VLAN support. Perfect for a small cluster network. Managed enough for VLANs without enterprise complexity.
APC BE600M1 UPS (600VA) - Power protection for your cluster. A proper UPS prevents split-brain scenarios caused by power blips and gives you time for graceful shutdowns.
Frequently Asked Questions
How many nodes do I need for a Proxmox cluster?
Plan on either three nodes for straightforward majority quorum or two nodes plus a QDevice / witness when budget is tighter. The key is to design quorum intentionally instead of discovering the requirement after the cluster is already carrying important workloads.
Can I run a Proxmox cluster on old desktops or laptops?
Yes, as long as they have 64-bit CPUs with virtualization support (VT-x/AMD-V), at least 8GB RAM, and gigabit Ethernet. Old Dell OptiPlex, Lenovo ThinkCentre, or HP EliteDesk machines work great. The main limitation is network ports - most desktops only have one NIC, so you'll need USB Ethernet adapters or VLANs for dedicated cluster networking.
What happens if my cluster loses quorum?
If more than half your nodes go down, the cluster loses quorum and stops fencing. VMs are shut down to prevent split-brain. With 3 nodes, losing 2 nodes means losing quorum. With a QDevice on a 2-node cluster, losing both nodes + the QDevice means losing quorum. The cluster will automatically recover when enough nodes come back online.
Is a Proxmox cluster overkill for a homelab?
It depends on your goals. If you just want to run a media server and some self-hosted apps, a single node is fine. If you want to learn enterprise virtualization, need HA for critical services, or want to do maintenance without downtime, a cluster is worth the investment. There's also significant learning value in running a cluster - you'll understand distributed systems concepts that are valuable in professional IT.
How do I back up VMs across a cluster?
Use Proxmox Backup Server (PBS) - it integrates directly with the cluster. Install PBS on a separate machine (or a VM on one node), add it as a storage target in Proxmox, and configure backup jobs at the Datacenter level so they follow VMs across nodes. For simpler setups, you can also back up to NFS storage directly from each node.
Final Thoughts
Building a Proxmox cluster is one of the most rewarding homelab projects you can take on. It teaches you real infrastructure skills - networking, storage, high availability, and distributed systems - that translate directly to professional IT work.
Start simple: bring up the nodes, verify quorum, validate storage visibility, test migration, then enable HA. Adding every advanced feature at once makes rollback and troubleshooting harder than it needs to be.
The journey from single-node to cluster is also worth documenting. Check our guide to growing your homelab for tips on scaling infrastructure without breaking everything.
A cluster is only as trustworthy as its tested recovery path. Document the expected failover behavior, test it during controlled maintenance windows, and update the plan when the hardware or storage design changes.
Marcus Chen is a senior systems engineer with 10+ years in enterprise IT and a homelab that's grown well beyond "reasonable." When he's not writing about infrastructure, he's usually fixing something he broke on purpose.
Sources and verification
Last verified: 2026-08-01. This article was reviewed against the primary documentation listed below. Unsupported first-person or faux-tested framing was removed unless the claim was backed by a cited primary source.