Docker Health Checks for Compose: Probes That Reflect Real Service Readiness
Learn how Docker health checks really work, how to pair them with Compose startup ordering, and how to pick probes that reflect service readiness instead of process uptime.
A Docker container can stay running long after the service behind it has stopped answering requests, lost database access, or stalled during startup. Health checks exist to separate process uptime from real service readiness, which is the signal that actually matters when a homelab stack has dependencies and shared failure domains.
The most useful probes are the ones that test the behavior a dependent service cares about, not just whether a process exists. This guide uses Docker's health-check and Compose startup-order documentation to show when a probe is worth adding, what a truthful readiness check looks like, and how to avoid checks that only create a false sense of safety.
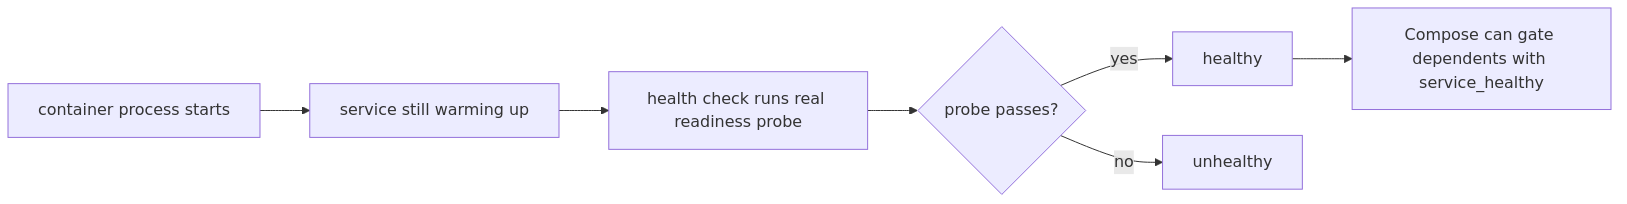
Docker health-check flow: a running process is only the starting point; the useful signal is whether the readiness probe passes before Compose lets dependent services move forward.
Key Takeaways
A running container is not the same thing as a healthy service.
Docker HEALTHCHECK marks state as starting, healthy, or unhealthy, but it does not restart a failed container by itself.
The best health checks test the thing that matters - not just whether a process exists.
docker compose health checks become much more useful when paired with depends_on: condition: service_healthy.
Lazy probes are worse than no probes. If your check always passes, you are just cosplaying observability.
docker inspect gives you the health log you need when a container flips to unhealthy.
Why health checks matter more in a homelab than people admit
In production, everybody talks about resilience. In homelabs, people often settle for vibes.
That is usually fine right up until your reverse proxy boots faster than your database, your app starts before migrations finish, or your monitoring stack tells you everything is green because the container process still exists. That is how you end up debugging a service that is technically running and practically broken.
A good health check gives Docker one honest answer to one useful question: is this service actually doing its job?
Docker runs a command inside the container on a schedule.
If the command exits with 0, the container is healthy. If it fails enough times in a row, Docker marks the container unhealthy.
The health states are simple:
starting - Docker is still in the early startup grace window
healthy - the latest checks passed
unhealthy - the check failed retries times in a row
That state appears in docker ps, docker inspect, and Compose tooling.
What Docker does not do is just as important.
A health check does not automatically restart the container. That part still belongs to restart policies, Compose behavior, or external automation. This is the mistake I see constantly, and yes, I made it too. I assumed unhealthy meant Docker would heroically save me from myself. It did not.
That only tells me the process exists. A process can exist while the app is wedged, misconfigured, or unable to serve requests.
transmission signup
article_topic // Docker Health Checks for Compose
Don't leave without the setup notes.
Get practical homelab guides, failure logs, and beginner-friendly build notes in your inbox.
Enter your email address to receive the Homelab Addiction newsletter.
Weekly only. No spam. Unsubscribe anytime.
Then I swung too far the other direction and wrote checks that were too clever. They tested every dependency, every route, and half my application logic. Those checks flapped constantly and turned normal startup into chaos.
The sweet spot is boring and specific.
A good health check should answer one practical question:
for a web app: can it answer a lightweight local request?
for Postgres: is the database ready to accept connections?
for Redis: does PING work?
for a worker: can the process respond to a minimal built-in status command?
If you can keep the probe fast, local, and meaningful, you are in good shape.
The timing knobs that matter
Docker gives you four controls that determine how health checks behave:
interval - how often to run the check
timeout - how long the check can take before it counts as failed
retries - how many consecutive failures before Docker marks it unhealthy
start_period - grace time after startup before failures count fully
A sane default for many self-hosted web apps looks like this:
That setup checks every 30 seconds, allows five seconds per check, waits through a 20-second startup period, and only declares failure after three misses.
Why does start_period matter? Because some services are slow to initialize, especially when they run migrations, warm caches, or wait for storage. Without a grace period, Docker starts screaming before your app has put its shoes on.
Health checks in a Dockerfile vs Compose
You can define a health check in the Dockerfile:
FROM node:22-alpine
WORKDIR /app
COPY package*.json ./
RUN npm ci
COPY . .
RUN apk add --no-cache curl
HEALTHCHECK --interval=30s --timeout=5s --start-period=20s --retries=3 \
  CMD curl -fsS http://localhost:3000/health || exit 1
CMD ["node", "server.js"]
That bakes the check into the image, which is great if the image always runs the same service with the same expectation.
You can also define it in Compose, which is what I do more often in a homelab because it keeps deployment behavior close to the stack config:
This is also where it helps to pair health checks with a solid proxy setup. If you are already running Nginx Proxy Manager on Docker or debugging daemon proxy issues, this is one more place where local HTTP truth beats assumptions.
5. Worker probe
Workers are trickier because they may not expose HTTP.
I prefer a command that proves the worker runtime is alive and can reach the system it depends on. That might be a queue ping, a lightweight application command, or a process-specific status endpoint.
Keep that script narrow. If your health check becomes a full integration test, you built a monitoring system with worse ergonomics.
A Compose example I would actually run
Here is a realistic stack with an app, Postgres, and Redis. This is the kind of setup where health checks stop being optional and start saving you time.
First, each service reports whether it is actually usable. Second, the app waits for the database and cache to become healthy before startup dependencies resolve. That alone kills a surprising amount of flaky boot behavior.
From the lab
Commands I use to verify health checks are real
After you define the check, do not just admire the YAML and move on. Test it.
That log view is one reason I keep recommending solid container logging habits. If you need a refresher, this Docker logs guide covers the basics cleanly.
How to test a failure on purpose
You should break the service deliberately once.
Yes, really.
If you never test the failure mode, you do not know whether your check is honest.
A few examples:
Break the HTTP endpoint
If your app exposes /healthz, stop the internal service or temporarily point the endpoint at something invalid.
Break database connectivity
Change the database host in a test stack or stop Postgres briefly:
docker compose stop postgres
Then watch the app health transition.
Break Redis
docker compose stop redis
Then confirm whether your worker or app reports failure the way you expect.
What you are looking for is simple:
does the container move from healthy to unhealthy when the real function breaks?
does it stay healthy during normal startup?
does it avoid flapping on harmless transient delays?
If the answer to those is yes, the probe is probably good.
Common mistakes
1. Using a port-open check as proof the app is healthy
A listening port only proves something is listening.
It does not prove the app can serve a real request, talk to its database, or return anything besides an error page.
2. Forgetting that the check runs inside the container
localhost means the container itself, not the host.
I still see people write health checks that assume host networking behavior. That road leads to confusion and muttering.
3. Not installing the probe tool
If your image does not include curl, wget, pg_isready, or redis-cli, the health check fails because the command does not exist. Docker is not being unfair here. It is being extremely literal.
4. Making the check too expensive
A health check should be cheap.
Do not run a heavy SQL query, hit five upstream APIs, or perform a mini synthetic transaction every ten seconds unless you enjoy creating your own incidents.
5. Expecting unhealthy to trigger restarts automatically
This one deserves repetition.
Health status is a signal. Restart behavior is separate. If you want automatic recovery, pair health checks with restart policy, external monitoring, or orchestration logic.
6. Skipping start_period
Without a startup grace period, slower apps can fail a few checks during boot and look sick before they are actually ready.
How health checks fit into the bigger reliability picture
Health checks are not full monitoring.
They are one of the cheapest local truth signals you can add to a stack, and they become more useful when combined with alerting and telemetry. In my own setups, they sit alongside uptime monitoring, logs, and metrics. If you are already running Prometheus and Grafana, health state becomes another useful clue when a service behaves strangely.
They also work nicely with sane backup and recovery practices. A health check will not save your data, but it will tell you faster when a restored service did not come back cleanly. That matters whether you use Restic for offsite copies or a more storage-heavy plan.
Recommended gear for a reliable Docker host
You do not need expensive hardware for health checks, but stable hosts make debugging much less irritating.
Fanless N100 mini PC with 2.5GbE - a solid low-power Docker box for small self-hosted stacks
https://www.amazon.com/s?k=fanless+n100+mini+pc+2.5gbe&tag=homelabaddiction-20
APC Back-UPS 1500VA - because clean shutdowns are cheaper than filesystem regret
https://www.amazon.com/s?k=apc+back-ups+1500va&tag=homelabaddiction-20
Samsung T7 Shield SSD - handy for quick config backups, compose repos, and emergency copies
https://www.amazon.com/s?k=samsung+t7+shield+ssd&tag=homelabaddiction-20
What to learn next
If you have health checks working, the next steps that actually compound are:
standardize your Compose files
add basic metrics and uptime checks
harden exposed services
back up the stack metadata and data volumes properly
Does Docker restart an unhealthy container automatically?
No. A health check changes health status. It does not, by itself, restart the container. Automatic recovery depends on restart policy, Compose behavior, or external tooling.
Should every container have a health check?
Not necessarily. Stateless web apps, databases, caches, and important workers usually benefit. Tiny one-shot helpers or containers with no meaningful runtime service boundary often do not need one.
What is the best command for a Docker health check?
The best command is the cheapest command that proves the real service is working. For web apps, that is usually a local HTTP request. For Postgres, pg_isready is better than a raw port check. For Redis, redis-cli ping is usually enough.
Why does my container stay unhealthy even though it is running?
Because running only means the main process still exists. Your health check may be failing due to bad config, dependency failures, missing probe tools, slow startup, or an endpoint that returns an error.
Is depends_on: condition: service_healthy worth using?
Yes, especially in self-hosted multi-service stacks. It reduces race conditions during startup and makes Compose bring services up in a more useful order.
Final opinion
Docker health checks are one of those features people ignore until they spend an evening debugging a container that is technically alive and functionally dead.
Use simple checks. Use honest checks. Test failure on purpose once. Then let Docker tell you something useful for a change.
transmission signupstatus: open channel
article_topic // Docker Health Checks for Compose
Start building a smarter homelab.
Join readers learning Proxmox, networking, storage, backups, and self-hosting without breaking everything.
Enter your email address to receive the Homelab Addiction newsletter.
Beginner-friendly
No gatekeeping. Just clear, actionable guides.
1 useful email / week
Practical tips, real-world setups, and lessons learned.
Zero hype, practical only
What works, what breaks, and how to fix it.
Reply to any email with what you're building. I read and reply to as many as I can.
— The Homelab Addiction Operator
support // the lab
Found this guide useful?
If it saved you time or a rebuild, you can support more practical homelab guides.