Homelab Monitoring with Prometheus and Grafana: A Practical Stack for Hosts, Containers, and Alerts
Set up a practical homelab monitoring stack with Prometheus, Grafana, Alertmanager, node_exporter, and cAdvisor. This refresh focuses on documented metrics coverage, placement, and alert scope.
FTC disclosure: This article contains affiliate links. If you purchase through these links, HomelabAddiction may earn a commission at no additional cost to you.
Documentation basis: This refresh is based on primary vendor or project documentation. No hands-on testing is claimed unless explicitly stated. Primary sources used in this refresh:
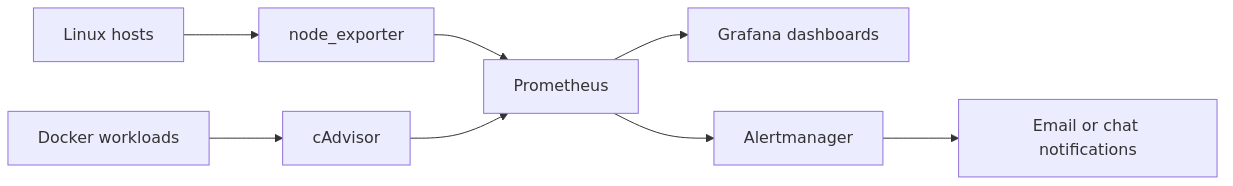
Figure: a simple Prometheus and Grafana monitoring path for Linux hosts, Docker workloads, dashboards, and alerts.
Key Takeaways
For most homelabs, Prometheus plus Grafana, node_exporter, cAdvisor, and Alertmanager cover the useful baseline without overbuilding the stack.
Host metrics and container metrics answer different questions, so collect both instead of assuming container graphs describe the whole machine.
Start with a short alert list focused on disk, memory pressure, failed scrapes, and backup-health signals before layering on more noise.
Keep Grafana and Prometheus on a management path or behind authenticated remote access rather than exposing them directly to the public internet.
Dashboards matter most when they shorten time to diagnosis, not when they maximize widget count.
This page helps homelab operators build a monitoring stack that surfaces host, container, and backup problems early by providing a documented Prometheus-and-Grafana baseline for small labs.
The refresh is grounded in Prometheus, Grafana, and node_exporter documentation. No hands-on testing is claimed unless explicitly stated on the page.
A simple layout is usually enough: collect host metrics with node_exporter, container metrics with cAdvisor, store them in Prometheus, visualize them in Grafana, and route only the alerts that you will actually act on.
What this stack is actually for
A lot of people start with uptime checks.
That is fine. Uptime Kuma is useful. A ping check is useful. "Can I hit port 443?" is useful.
But uptime checks only answer whether something is alive right now. They do not tell you that RAM has been climbing all week, disk I/O is getting ugly during backups, or that your Docker host has quietly been swapping like it is 2012.
Prometheus and Grafana fill that gap.
Prometheus scrapes and stores metrics.
Grafana turns those metrics into dashboards and alerts you can actually read.
node_exporter exposes host-level Linux metrics.
cAdvisor exposes container metrics.
Alertmanager routes alerts somewhere useful.
That covers almost every small-to-medium homelab use case that matters.
A practical architecture
For a real homelab, keep the layout simple:
Run Prometheus, Grafana, Alertmanager, and cAdvisor on one monitoring host.
Run node_exporter on each Linux server or VM you care about.
Scrape everything from Prometheus every 15 to 30 seconds.
Store 30 to 90 days of data depending on disk space and how much trend history you care about.
If you already have a management VLAN, put the monitoring stack there. If not, at least avoid exposing Grafana directly to the internet. A reverse proxy plus SSO or VPN access is the civilized option.
If you are already segmenting your network, my homelab network segmentation guide will help you place this stack somewhere sensible. Monitoring belongs in the "important, boring, do not poke it" part of the lab.
Resource sizing - what a homelab actually needs
This is one of those topics that gets overcomplicated fast.
For most homelabs, a monitoring stack does not need enterprise hardware. It needs enough RAM, enough SSD space, and enough discipline to avoid scraping every nonsense metric at 5-second intervals.
Here is a sizing baseline:
transmission signup
article_topic // Homelab Monitoring with Prometheus and Grafana
Don't leave without the setup notes.
Get practical homelab guides, failure logs, and beginner-friendly build notes in your inbox.
Enter your email address to receive the Homelab Addiction newsletter.
Weekly only. No spam. Unsubscribe anytime.
Homelab size
Prometheus + Grafana host recommendation
Retention
1-3 servers, light Docker usage
2 vCPU, 2 GB RAM, 20-30 GB SSD
30 days
4-10 servers, moderate containers
2-4 vCPU, 4 GB RAM, 40-80 GB SSD
60-90 days
10+ servers, many exporters and dashboards
4 vCPU, 8 GB RAM, 100+ GB SSD
90 days
For a small lab, even a tiny mini PC or VM is fine.
Hardware that fits this role
Raspberry Pi 5 starter kit: https://www.amazon.com/s?k=raspberry+pi+5+8gb+starter+kit&tag=homelabaddiction-20
Beelink S12 Pro mini PC: https://www.amazon.com/s?k=beelink+s12+pro+mini+pc&tag=homelabaddiction-20
APC UPS for the monitoring node and switch: https://www.amazon.com/s?k=apc+bx1500m+ups&tag=homelabaddiction-20
No, you do not need a dedicated rackmount server just to learn whether /var is filling up. Let us stay emotionally grounded.
The Docker Compose stack
This is the starting point I recommend for the monitoring node.
If the targets are healthy, you are already ahead of most abandoned monitoring projects.
Why node_exporter usually belongs natively on Linux hosts
You can run node_exporter in a container.
You can also microwave leftover pizza in a cast-iron pan if you are creative enough. The fact that something is possible does not make it the better default.
For host metrics, native installation is cleaner and more trustworthy. It avoids weird path mapping mistakes, avoids container abstraction problems, and makes it obvious that you are monitoring the host rather than a carefully cropped version of the host.
sudo systemctl daemon-reload
sudo systemctl enable --now node_exporter
sudo systemctl status node_exporter
curl -s http://localhost:9100/metrics | head
That last command matters.
If you do not verify that metrics are actually being exposed before editing Prometheus targets, you are creating a future troubleshooting session for yourself. Future-you is rarely grateful.
What to monitor first
This is where many people overbuild.
You do not need 40 dashboards on day one. You need the first 10 things that catch real problems.
Start with these:
1. CPU saturation
Watch sustained CPU pressure, not brief spikes.
A backup job hitting 90% CPU for thirty seconds is normal. A host sitting at 90% for fifteen minutes while Docker containers time out is not.
2. Memory pressure and swap use
Swap is not always evil. Surprise swap is usually annoying.
If a box that should idle comfortably starts leaning on swap every day, something changed. That is the story metrics are good at telling.
3. Disk space and inode usage
Disk alerts are the most boring alerts in the world.
They are also the ones that save the most services.
4. Disk I/O latency and filesystem pressure
This matters a lot during backups, scrubs, media imports, and VM-heavy workloads.
If you already read my article on Proxmox backup strategies, you know backup windows are where storage lies get exposed very quickly.
5. Network throughput and dropped packets
You do not need to graph every packet forever.
You do need to know when a link is saturating or when traffic patterns suddenly change.
6. Container restarts and resource usage
cAdvisor helps you see which container is chewing RAM, thrashing CPU, or quietly restarting itself every few minutes while pretending everything is fine.
Once the basics are stable, build one dashboard that reflects your lab:
- backup host health
- Proxmox storage nodes
- main Docker host
- NAS utilization
- internet edge/router stats if you export them
That is the dashboard you will actually look at.
Security and placement rules
This part gets ignored too often.
Monitoring systems accumulate infrastructure details fast - hostnames, ports, disk layouts, service labels, and enough metadata to make an attacker's day slightly more organized.
Useful defaults:
do not expose Grafana directly to the public internet
put Prometheus and Grafana on a management VLAN or restricted subnet
use a reverse proxy with auth if remote access is required
prefer VPN access for admin usage
rotate default Grafana credentials immediately
back up Grafana data and Prometheus config like any other critical service
If your Compose stack still needs cleanup, review my piece on Docker Compose best practices. Monitoring should not be the messiest application in the environment it is supposed to observe.
Common mistakes
Monitoring only containers, not hosts
Container graphs are useful.
They are not enough when the host kernel, disk layer, or memory pressure is the real problem.
Using too many exporters too early
You do not need SNMP, blackbox checks, process exporters, Postgres exporters, and custom scripts before you even know whether your main node is filling its root partition.
Start narrow. Expand on purpose.
Scraping too aggressively
A 5-second scrape interval looks energetic.
It also burns storage faster and rarely helps a small lab. Fifteen seconds is a sensible default. Thirty is fine for less critical targets.
Ignoring retention
Prometheus will happily store data until you discover your monitoring host needs monitoring.
Set retention intentionally.
Treating alerts like decorations
If an alert does not lead to action, either fix it or delete it.
A noisy monitoring stack teaches you to ignore the right warnings along with the bad ones.
My recommended rollout order
If you want the shortest path to a useful setup, do it in this order:
Deploy Prometheus and Grafana on one monitoring node.
Install node_exporter on one Linux host.
Confirm host metrics are visible in Prometheus.
Import one node dashboard in Grafana.
Add cAdvisor for container metrics.
Add two or three more hosts.
Enable only a handful of high-value alerts.
Back up the config and dashboard data.
That sequence gives you a real win quickly.
It also avoids the classic homelab trap of spending six hours perfecting a stack you never quite finish using.
FAQ
Do I need both Prometheus and Grafana?
Technically, no. Prometheus can show raw queries and basic graphs.
Practically, yes. Grafana is what makes the data easy to read, compare, and alert on without feeling like you are interrogating a database during a hostage situation.
Should node_exporter run in Docker or as a systemd service?
For host metrics, a native systemd service on Linux machines is usually the cleaner default.
It is simpler to reason about and less likely to misreport the host because of container path mapping or permission quirks.
Is Alertmanager overkill for a small homelab?
Not if you keep the alert list short.
Alertmanager becomes overkill when people feed it every possible warning and then blame the tool for their own lack of restraint.
How much storage does Prometheus need?
For a small homelab, 20-40 GB is usually plenty for a 30- to 60-day window.
If you scrape many hosts, many exporters, or use aggressive intervals, budget more SSD space and review retention before Prometheus helpfully eats the disk it is supposed to monitor.
Can one stack monitor Proxmox, Linux VMs, and Docker together?
Yes. That is one of the best reasons to use this stack.
Prometheus does not care whether a metric came from a Docker host, a VM, a Proxmox exporter, or a physical Linux box. It just cares that the target exposes metrics cleanly.
Final recommendation
If your homelab has grown beyond "one box and a dream," build this stack.
Not because it is fashionable. Because it gives you trend data, real troubleshooting context, and a way to see problems before users, family members, or your own bad decisions discover them first.
Keep the first version small.
Monitor hosts, monitor containers, alert on the obvious failures, and lock the stack down properly. You can always grow into more exporters later. You do not get bonus points for building a monitoring cathedral before you have a usable dashboard.
That is a practical default stack. It has saved me from bad storage windows, noisy containers, and at least a few episodes of deeply undeserved confidence.
transmission signupstatus: open channel
article_topic // Homelab Monitoring with Prometheus and Grafana
Start building a smarter homelab.
Join readers learning Proxmox, networking, storage, backups, and self-hosting without breaking everything.
Enter your email address to receive the Homelab Addiction newsletter.
Beginner-friendly
No gatekeeping. Just clear, actionable guides.
1 useful email / week
Practical tips, real-world setups, and lessons learned.
Zero hype, practical only
What works, what breaks, and how to fix it.
Reply to any email with what you're building. I read and reply to as many as I can.
— The Homelab Addiction Operator
support // the lab
Found this guide useful?
If it saved you time or a rebuild, you can support more practical homelab guides.